work / ops-fleet
Ops and the ticket fleet
The control plane: nightly dependency audits and health checks, plus a ticket queue that hands written specs to coding agents.
- status
- private
- year
- 2026
- stack
- FastAPI
- Redis Streams
- Jinja2
- OpenCode
The problem
With dozens of services, "is everything fine?" can't be answered from memory, and small dependency bumps pile up faster than one person can apply them by hand.
What I built
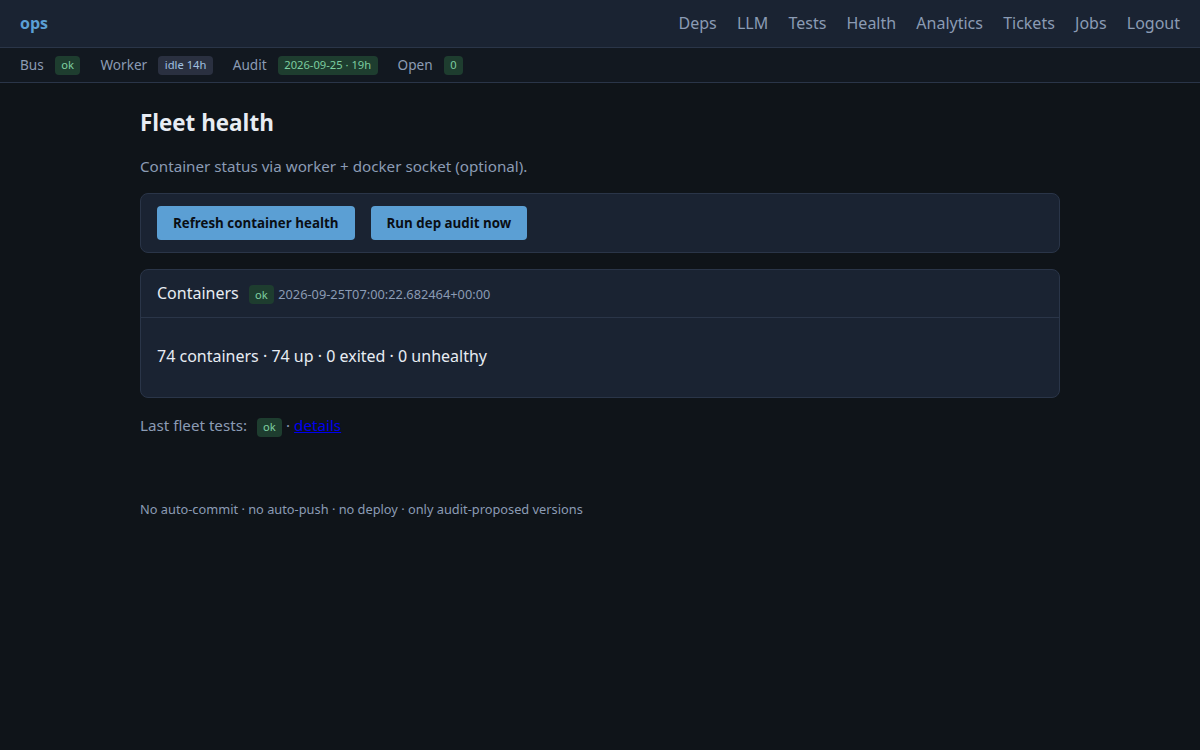
Ops is the fleet's control plane. It keeps a dependency audit for every repo and publishes upgrade jobs to the event bus; a separate worker applies each bump, runs that repo's tests and reports back. At 2 a.m. a nightly run checks health across the fleet and sends one summary email.
The same app runs the ticket board. A ticket is a written spec and plan, committed to the repo it changes. The board queues tickets and hands them, one at a time, to coding agents running on the local GPU, then shows where each session stands.
Where it stands
In daily use, with over a hundred tickets filed. Checks that need the host run in a separate host-side script and pass their findings in.